Variational Quantum Algorithms
Theory of variational quantum algorithms including the variational principle, VQE, QAOA, barren plateaus, and gradient computation methods. This guide connects the theoretical foundations to pyqpanda3's variational quantum circuit (VQC) framework.
The Variational Principle
Rayleigh-Ritz Variational Principle
The foundation of all variational quantum algorithms is the Rayleigh-Ritz variational principle:
For any parameterized quantum state
and any Hamiltonian , the expectation value of the energy provides an upper bound on the ground state energy :
Equality holds if and only if
Energy as a Cost Function
The variational principle allows us to formulate the ground state problem as an optimization:
The loss function (energy) is:
This loss function has important properties:
- Non-negative curvature:
- Smooth:
is a smooth function of for analytic ansatzes - Observable:
can be estimated from quantum measurements
Variational Quantum Circuits as Trial States
In pyqpanda3, the trial state
where
The VQC is constructed using pyqpanda3's VQCircuit class:
from pyqpanda3.vqcircuit import VQCircuit
from pyqpanda3.core import RY, CNOT

# Build a hardware-efficient ansatz
# set_Param initializes the parameter array dimensions for the circuit
vqc = VQCircuit()
vqc.set_Param([4])
vqc << RY(0, vqc.Param([0], "theta_0"))
vqc << RY(1, vqc.Param([1], "theta_1"))
vqc << CNOT(0, 1)
vqc << RY(0, vqc.Param([2], "theta_2"))
vqc << RY(1, vqc.Param([3], "theta_3"))
Expressibility
The expressibility of a VQC measures how well it can explore the Hilbert space. A perfectly expressible ansatz generates the Haar-uniform distribution of unitaries. Less expressible ansatzes may not be able to reach the optimal solution.
Expressibility is measured by the deviation from the Haar distribution:
A well-designed ansatz balances expressibility against trainability (avoiding barren plateaus).
VQE — Variational Quantum Eigensolver
Algorithm Overview
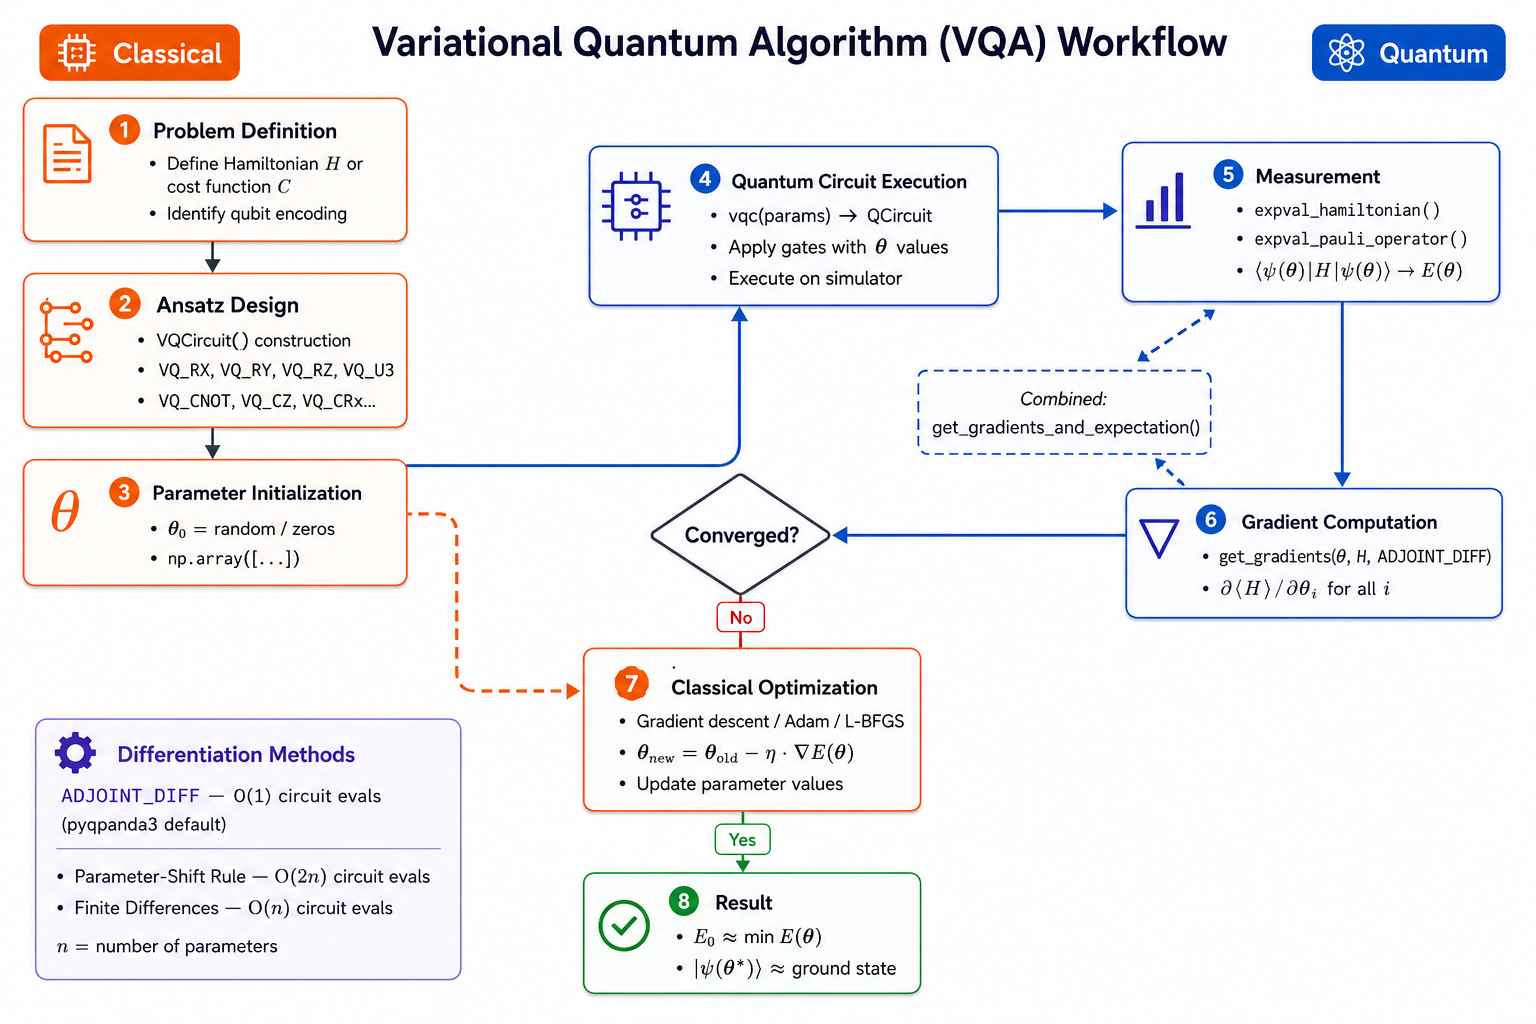
The Variational Quantum Eigensolver (VQE) is a hybrid quantum-classical algorithm for finding the ground state energy of a Hamiltonian:
graph TD
    Start["Define Hamiltonian H"] --> Ansatz["Choose Ansatz VQCircuit"]
    Ansatz --> Init["Initialize θ"]
    Init --> Quantum["Prepare |ψ(θ)⟩<br/>Measure ⟨H⟩"]
    Quantum --> Classical["Classical Optimizer<br/>Update θ"]
    Classical --> Converge{"Converged?"}
    Converge -->|No| Quantum
    Converge -->|Yes| Result["E₀ ≈ min ⟨H⟩"]

    style Quantum fill:#e3f2fd,stroke:#1565c0
    style Classical fill:#fff3e0,stroke:#e65100
    style Result fill:#c8e6c9,stroke:#2e7d32
Hamiltonian Decomposition
To measure the energy on a quantum computer, the Hamiltonian must be decomposed into measurable Pauli strings:
where
The energy expectation is then:
Each
pyqpanda3 provides:
pyqpanda3.core.expval_hamiltonian(prog, hamiltonian, shots=1, model=..., used_threads=4, backend='CPU')— direct expectation value computation from a quantum programpyqpanda3.core.expval_pauli_operator(prog, pauli_operator, shots=1, model=..., used_threads=4, backend='CPU')— Pauli operator expectation
Ansatz Design Strategies
Hardware-Efficient Ansatz:
Designed to match the native gate set and connectivity of the target hardware:
where ENTANGLE is a layer of CNOT gates matching the hardware topology.
- Pros: Shallow depth, native gates, fewer SWAP overhead
- Cons: May require many layers, susceptible to barren plateaus
Chemically-Inspired Ansatz (Unitary Coupled Cluster):
Based on the unitary coupled cluster singles and doubles (UCCSD):
where
- Pros: Physically motivated, few parameters for small molecules
- Cons: Deep circuits, requires Trotterization
Adaptive Ansatz (ADAPT-VQE):
Grow the ansatz iteratively by adding the operator with the largest gradient:
where
- Pros: Compact ansatz, systematic construction
- Cons: Requires gradient pool evaluation at each step
Classical Optimization
The classical optimizer updates parameters to minimize the energy:
Common optimizers used with VQE:
| Optimizer | Type | Pros | Cons |
|---|---|---|---|
| Gradient Descent | First-order | Simple, stable | Slow convergence |
| Adam | First-order (adaptive) | Fast, robust | May oscillate |
| L-BFGS-B | Quasi-Newton | Superlinear convergence | Noisy gradient sensitive |
| COBYLA | Derivative-free | Handles noise | Slow for many parameters |
| SPSA | Stochastic | Noise-tolerant, | Slow convergence |
| SNOBFIT | Surrogate model | Good for noisy landscapes | Expensive per iteration |
Shot Noise and Statistical Error
The energy estimate has statistical uncertainty from finite measurement shots:
where
Rule of thumb: Doubling the accuracy requires
Convergence Analysis
VQE convergence depends on:
- Ansatz quality: Can the ansatz reach the ground state?
- Optimizer efficiency: How quickly does the optimizer find the minimum?
- Noise resilience: How much does noise affect the energy estimate?
VQE is generally considered noise-resilient because:
- The variational principle still holds (noisy energy is still an upper bound)
- The optimizer can partially compensate for systematic noise
- Error bars from shot noise can guide the optimizer
QAOA — Quantum Approximate Optimization Algorithm
Algorithm Overview
QAOA is designed for combinatorial optimization problems. Given a cost function
where:
is the cost Hamiltonian (diagonal in computational basis) is the mixer Hamiltonian and are the variational parameters is the QAOA depth (number of alternating layers)
graph LR
    Plus["|+⟩^⊗n"] --> L1["e^{-iγ₁H_C}"]
    L1 --> M1["e^{-iβ₁H_M}"]
    M1 --> L2["e^{-iγ₂H_C}"]
    L2 --> M2["e^{-iβ₂H_M}"]
    M2 --> Dot["..."]
    Dot --> LP["e^{-iγ_P H_C}"]
    LP --> MP["e^{-iβ_P H_M}"]
    MP --> Measure["Measure<br/>⟨H_C⟩"]

    style L1 fill:#f8cecc,stroke:#b85450
    style L2 fill:#f8cecc,stroke:#b85450
    style LP fill:#f8cecc,stroke:#b85450
    style M1 fill:#dae8fc,stroke:#6c8ebf
    style M2 fill:#dae8fc,stroke:#6c8ebf
    style MP fill:#dae8fc,stroke:#6c8ebf
MaxCut Example
The canonical QAOA application is MaxCut. Given a graph
Cost Hamiltonian:
This assigns energy
Mixer Hamiltonian:
QAOA circuit construction:
Each cost layer
Each mixer layer
Approximation Ratio
The approximation ratio measures QAOA quality:
: for MaxCut on 3-regular graphs (guaranteed by QAOA theory) : (QAOA converges to optimal) - In practice,
to often achieves
QAOA Variants
| Variant | Description | Advantage |
|---|---|---|
| Standard QAOA | Fixed depth | Theoretical guarantees |
| Warm-Start QAOA | Initialize from classical solution | Better initial point |
| Recursive QAOA | Fix qubits iteratively | Reduces problem size |
| Multi-angle QAOA | Different angles per gate | More expressive |
| QAOA with constraints | Penalty terms in | Handles constrained problems |
Barren Plateaus
The Vanishing Gradient Problem
Barren plateaus occur when the gradient of the cost function vanishes exponentially with the number of qubits:
This means that for a system of
graph TD
    Shallow["Shallow Circuits<br/>(Few parameters)"] --> Trainable["Trainable Landscape<br/>Large gradients"]
    Deep["Deep Circuits<br/>(Many parameters)"] --> Barren["Barren Plateau<br/>Exponentially small gradients"]

    Expressible["High Expressibility"] --> Barren
    Entangled["High Entanglement"] --> Barren
    Noise["Hardware Noise"] --> Barren

    Local["Local Cost Functions"] --> Avoid["Avoid Barren Plateaus"]
    Structured["Structured Ansatz"] --> Avoid
    Parameters["Careful Initialization"] --> Avoid

    style Trainable fill:#c8e6c9,stroke:#2e7d32
    style Barren fill:#ffebee,stroke:#c62828
    style Avoid fill:#e3f2fd,stroke:#1565c0
Causes of Barren Plateaus
1. Expressibility-induced: Highly expressible ansatzes that cover the entire Hilbert space tend to concentrate cost function values around the mean, flattening the landscape.
2. Entanglement-induced: Deep entangling circuits produce global states where local parameter changes have exponentially small effects.
3. Noise-induced: Hardware noise flattens the cost landscape by driving all outputs toward the maximally mixed state.
4. Global cost functions: Cost functions that depend on all qubits simultaneously (e.g., global fidelity) exhibit barren plateaus even for shallow circuits.
Mitigation Strategies
1. Local Cost Functions:
Replace global cost functions with local ones:
Local cost functions have gradients that vanish polynomially rather than exponentially.
2. Structured Ansatz:
Use ansatzes with built-in structure (e.g., symmetry-preserving, problem-inspired):
- QAOA ansatz for combinatorial optimization
- UCCSD ansatz for chemistry
- Hardware-efficient ansatz with limited depth
3. Parameter Initialization:
- Identity initialization: Start with parameters close to the identity circuit (
) - Layer-by-layer training: Train one layer at a time, adding layers incrementally
- Classical pre-training: Use classical optimization to find a good initial point
4. Gradient Preserving Architectures:
- Use circuits where the gradient magnitude is provably lower-bounded
- Examples: quantum convolutional neural networks (QCNN), certain hierarchical circuits
Gradient Computation Methods
Overview
Computing gradients of the expectation value
graph TD
    Grad["Gradient Methods"] --> PS["Parameter-Shift Rule"]
    Grad --> AD["Adjoint Differentiation"]
    Grad --> FD["Finite Differences"]
    Grad --> LS["Linear Combination<br/>of Unitaries"]

    PS -->|"2 circuit evals per parameter"| Exact1["Exact gradient"]
    AD -->|"2 circuit evals total"| Exact2["Exact gradient"]
    FD -->|"2 circuit evals per parameter"| Approx["Approximate gradient"]
    LS -->|"O(1) circuit evals"| Exact3["Exact (with ancilla)"]

    style Exact1 fill:#c8e6c9,stroke:#2e7d32
    style Exact2 fill:#c8e6c9,stroke:#2e7d32
    style Exact3 fill:#c8e6c9,stroke:#2e7d32
    style Approx fill:#fff3e0,stroke:#e65100
Parameter-Shift Rule
The parameter-shift rule provides an exact gradient using two circuit evaluations per parameter:
where
For generators
Cost:
Advantages:
- Exact gradient (no approximation error)
- Hardware-compatible (only needs forward evaluations)
- Works with shot noise (statistical error only)
Adjoint Differentiation
Adjoint differentiation computes the gradient in ADJOINT_DIFF:
where
Algorithm (Jones & Gacon, 2020):
- Forward pass: compute
- Backward pass: apply gates in reverse, computing inner products
- Total: 2 circuit evaluations (one forward, one backward) regardless of parameter count
Cost: 2 circuit evaluations total.
Advantages:
- Dramatically faster for large parameter counts:
vs - Exact gradient
- Well-suited for simulation-based optimization
Limitations:
- Requires storing intermediate state vectors (memory:
) - Only applicable in statevector simulation, not hardware measurements
- Implementation-dependent on the simulator
Usage in pyqpanda3:
from pyqpanda3.vqcircuit import VQCircuit, DiffMethod
from pyqpanda3.hamiltonian import Hamiltonian
from pyqpanda3.core import RY, CNOT
import numpy as np

# Build a simple ansatz with 4 parameters
vqc = VQCircuit()
vqc.set_Param([4])
vqc << RY(0, vqc.Param([0], "theta_0"))
vqc << RY(1, vqc.Param([1], "theta_1"))
vqc << CNOT(0, 1)
vqc << RY(0, vqc.Param([2], "theta_2"))
vqc << RY(1, vqc.Param([3], "theta_3"))

params = np.array([0.1, 0.2, 0.3, 0.4])
observable = Hamiltonian({"Z0 Z1": 1.0, "X0": 0.5})

# Get gradients using adjoint differentiation
gradients = vqc.get_gradients(params, observable, DiffMethod.ADJOINT_DIFF)
# → ResGradients object containing gradients for all 4 parameters

# Get both gradients and expectation value simultaneously
result = vqc.get_gradients_and_expectation(params, observable, DiffMethod.ADJOINT_DIFF)
expectation = result.expectation_val()
# → expectation ≈ 0.957 (varies with parameters)
grads = result.gradients()
# → grads ≈ [0.202, -0.491, 0.265, -0.511] (varies with parameters)
Finite Differences
The simplest gradient approximation:
Cost:
Disadvantages:
- Approximation error
- Choosing
: too small → noise dominated; too large → approximation error - Not recommended for quantum computing due to shot noise sensitivity
Linear Combination of Unitaries (LCU)
An advanced method using ancilla qubits:
Can be implemented with Hadamard tests or iterative QPE, but requires ancilla qubits and controlled versions of gates.
Comparison Table
| Method | Circuit Evals | Exact? | Hardware? | Memory |
|---|---|---|---|---|
| Parameter-Shift | Yes | Yes | ||
| Adjoint (ADJOINT_DIFF) | 2 | Yes | No (simulation only) | |
| Finite Differences | No ( | Yes | ||
| LCU | Yes | Yes (with ancilla) |
For pyqpanda3 simulations, ADJOINT_DIFF is the recommended method due to its DiffMethod enum provides ADJOINT_DIFF as the available differentiation method.
Parameter Management in pyqpanda3
Multi-Dimensional Parameters
pyqpanda3 supports multi-dimensional parameter arrays through the set_Param() and Param() methods:
vqc = VQCircuit()

# Set parameter dimensions: e.g., 3 layers × 4 parameters
vqc.set_Param([3, 4], ["layer", "param"])

# Access a specific parameter element
theta_00 = vqc.Param([0, 0], "theta_00")  # Layer 0, param 0
theta_12 = vqc.Param([1, 2], "theta_12")  # Layer 1, param 2
This is useful for:
- Batch optimization: Evaluate gradients for multiple parameter sets simultaneously
- Structured ansatzes: Map parameters to physical structure (e.g., layer × qubit)
- Transfer learning: Share parameters between circuit blocks
Batch Gradient Computation
For
import numpy as np
from pyqpanda3.vqcircuit import VQCircuit, DiffMethod
from pyqpanda3.hamiltonian import Hamiltonian
from pyqpanda3.core import RY, CNOT

# Build the same ansatz as above
vqc = VQCircuit()
vqc.set_Param([4])
vqc << RY(0, vqc.Param([0], "theta_0"))
vqc << RY(1, vqc.Param([1], "theta_1"))
vqc << CNOT(0, 1)
vqc << RY(0, vqc.Param([2], "theta_2"))
vqc << RY(1, vqc.Param([3], "theta_3"))

observable = Hamiltonian({"Z0 Z1": 1.0, "X0": 0.5})

# Single parameter set
params_1d = np.array([0.1, 0.2, 0.3, 0.4])
grads = vqc.get_gradients(params_1d, observable, DiffMethod.ADJOINT_DIFF)
# → ResGradients (1 set of gradients)

# N parameter sets (flat array, row-major order)
params_flat = np.array([0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8])
N = 2
grads_n = vqc.get_gradients(params_flat, observable, N, DiffMethod.ADJOINT_DIFF)
# → ResNGradients (N sets of gradients)
Result Classes
| Class | Method | Returns |
|---|---|---|
ResGradients | get_gradients(params, H, diff) | Gradients for 1 parameter set |
ResNGradients | get_gradients(params, H, N, diff) | Gradients for N parameter sets |
ResGradientsAndExpectation | get_gradients_and_expectation(params, H, diff) | Gradients + expectation for 1 set |
ResNResGradientsAndExpectation | get_gradients_and_expectation(params, H, N, diff) | Gradients + expectation for N sets |
Practical Considerations
Ansatz Selection Guide
| Problem Type | Recommended Ansatz | Rationale |
|---|---|---|
| Molecular ground state | UCCSD / k-UpCCGSD | Chemically motivated, systematic improvability |
| Combinatorial optimization | QAOA | Theoretical guarantees, structured |
| General optimization | Hardware-efficient | Shallow depth, hardware-native |
| Quantum machine learning | Layered rotations + entanglement | Expressibility, trainable |
| Dynamical simulation | Trotterized evolution | Physically motivated |
Optimizer Selection Guide
| Scenario | Recommended Optimizer |
|---|---|
| Simulation (exact gradients) | L-BFGS-B with adjoint differentiation |
| Noisy simulation | Adam with learning rate scheduling |
| Hardware (shot noise) | SPSA or parameter-shift + Adam |
| Few parameters | COBYLA (derivative-free) |
| Many parameters | Adam or natural gradient methods |
Performance Tips
- Use adjoint differentiation when simulating:
vs gradient evaluations - Group Pauli measurements: Commuting Pauli strings can be measured simultaneously
- Use
get_gradients_and_expectation: Computes both in a single call, more efficient than separate computations - Warm-start from classical solutions: Initialize parameters from classically solvable approximations
- Monitor convergence: Track both energy and gradient norm; stop when gradient norm is below threshold
See Also
- VQCircuit API — Full API for variational quantum circuits
- DiffMethod — Differentiation method enum
- Gradient Results — ResGradients and related classes
- Hamiltonian — Hamiltonian construction
- VQA Workflow Diagram — Visual VQA optimization loop
- Quantum Gate Theory — Gate fundamentals
- Noise Model Theory — Noise in variational algorithms